


Home »
Content management in the museum
Digital content has become indispensable in museums. But what is the optimal way to create and post content when you need to coordinate different trades with each other?
These can be texts, images, videos, or audio recordings that run on dedicated players in the loop. This content must also be distributed and should be interchangeable at any time. In most cases, this is done using a file transfer, i.e. the content is copied directly to the playout systems (content push).
However, things get more complicated when this content is part of a larger interactive application. At the latest then one should no longer do without the use of a CMS. Because at that point, content exchange may become expensive. For example, if a programmer based in Munich has to recompile the application for a small text change and the application then has to be re-installed in Berlin. The applications should therefore be written or created in such a way that they fetch the content from a CMS server.

Content Management System — CMS is not just CMS.
CMS is not a protected term; it simply describes the fact that content is exchanged in some way and somewhere.
But you should pay very close attention to your own requirements. For example, if you search for the term “CMS” on the Internet, you’ll quickly come across the usual suspects like WordPress, Joomla, or Typo3. There are now countless content management systems, and each one fulfills one purpose or another—some better than others.
For example, if you want to build a blog, WordPress is a good choice, and for a website, Joomla or Typo3 aren’t bad options.
But what about when you have different interactive applications whose content you want to share individually — like in a museum, for example?
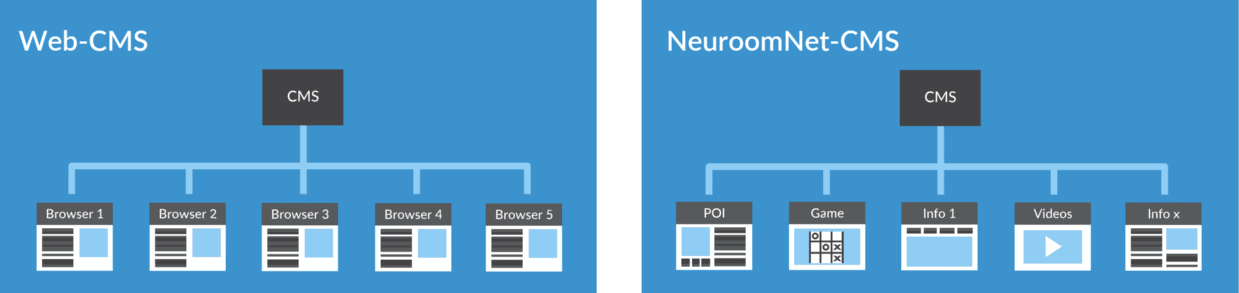
This reveals the major discrepancy compared to the traditional web CMS systems listed above. These systems are designed to create ONE source—for example, ONE blog with perhaps several subpages. This SINGLE source is, in turn, accessed by MANY devices—that is, many people view this blog using their browsers, and it looks the same to every viewer. In this case, the CMS also determines how the content is displayed, as well as the page’s behavior.
This brings us to the second criterion. In the case of the museum, there are different applications—for example, a game, an informational application, and a video slideshow. Their appearance and behavior should each be different—that is, individually programmed. But all applications should retrieve their data from ONE CMS. So the CMS is actually intended to provide content only and not worry about the appearance, but instead supply content for many different applications.
Today, this type of CMS is generally referred to as a headless CMS. NeuroomNet includes such a CMS. It provides an API —a well-defined interface—to give programmers a standardized way to retrieve content from a central location, which the museum can modify at any time.
This should be taken into account, especially in calls for proposals. This is because if a call for proposals specifies only a CMS, the result may be one of the web-based CMSs mentioned above. These tools are usually free to install but do not provide the desired functionality.
From the idea to the end product
Let’s assume we want to have software developed for a museum application. First, as with any good software, a requirements specification should be created—ideally with detailed screen designs. But the lines are blurred here, whether you choose the traditional approach or a more agile one.
However, if you plan to replace or supplement the content later, you should already have a reasonably clear idea at this stage of exactly which content this will affect. For example, if we have an application that lists all Nobel Prize winners along with relevant additional information, we’ll also want to be able to add new scientists. But if you write, “All content should be replaceable via a CMS,” you face two problems: first, the CMS isn’t defined (see above), and second, from the programmers’ perspective, the graphics on the buttons, the background image, and the button labels are also considered content. It’s possible that you’ll want to update this content as well, but if not, it will only drive up costs.
When will the data come?
Done and dusted, everything’s settled. The programmers can get to work. Meanwhile, the content is being created. No problem—the programmers can work with dummy data in the meantime. Sure, they can. But it’s good if the file formats are already clarified at this stage. Surprises like “Oh, but the images are too big/too small” or “We can’t import .doc files”—nobody needs that, and it usually leads to extra costs down the line.
Lucky are those who already have access to a CMS at this stage. If the CMS runs on the museum’s IT infrastructure, programmers, translators, graphic designers, etc.,“only” need a VPN to access the same data as the researchers and museum staff working in-house.
In practice, things usually look different. For example, when the museum is still under construction or undergoing renovations. Or at least when the IT infrastructure needs to be upgraded accordingly, or, or, or…
Let’s therefore focus on the most stress-free of all solutions. NeuroomNet hosts the CMS online for you during the development phase. Everyone involved uses, creates, and corrects the same data from the very beginning. Problems such as “too big,” “too small,” “too much text,” or “too little text” are noticed immediately—not only after the application is finished. In the end, when the application is installed on-site and NeuroomNet makes the CMS available locally at the museum, NeuroomNet simply migrates the data to the museum’s local IT system.
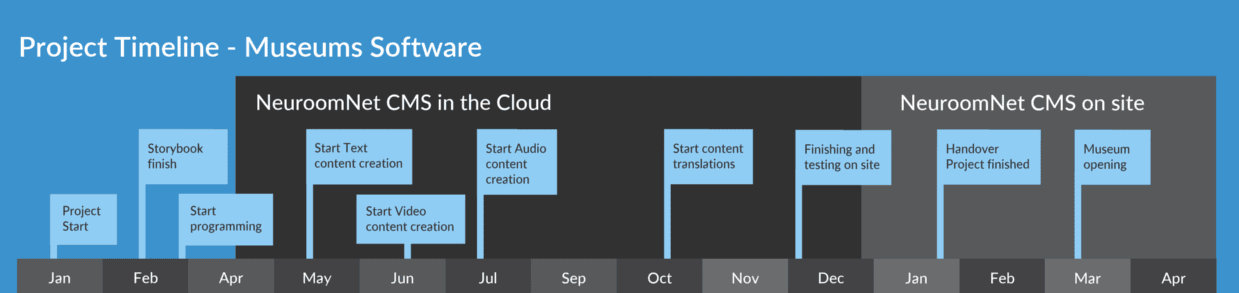
In an “all-around happy package,” we accompany you from consultation, planning, hardware procurement, installation, configuration, and commissioning to documentation and training of your staff.